Evaluate and compare AI tools with a reproducible test
A successful demonstration is not enough to select a tool. A useful comparison applies the same cases, authorised data and pre-defined scoring, while counting the human effort required to correct outputs.
The short answer
Prepare five to ten representative cases, including edge cases. Freeze inputs and criteria before testing. Record output, errors, human time, cost and recovery effort, retain evidence and plan an exit route.
- Test identical cases
- Count human correction
- Plan for reversibility
Create a comparable protocol
1. Define the decision
Clarify whether you are choosing a personal assistant, team tool, API or platform. List disqualifying requirements before looking at scores.
2. Build the test set
Select frequent, difficult and deliberately incomplete cases. Use fictional or authorised data, with a reference answer where possible.
3. Freeze the protocol
Use identical instructions, attachments, settings and number of attempts. Record the service version and date because results can change without notice.
4. Measure quality
Assess accuracy, completeness, instruction following, traceability and output quality. Define each score level to reduce arbitrary judgements.
5. Measure operations
Time preparation, generation, review, correction and export. Add licences, usage, integration, training, maintenance and the cost of errors.
6. Decide and monitor
Select according to requirements and net value, document trade-offs and schedule a new review. Retain the data and formats required to switch tools.
Put the method to work
Practical case
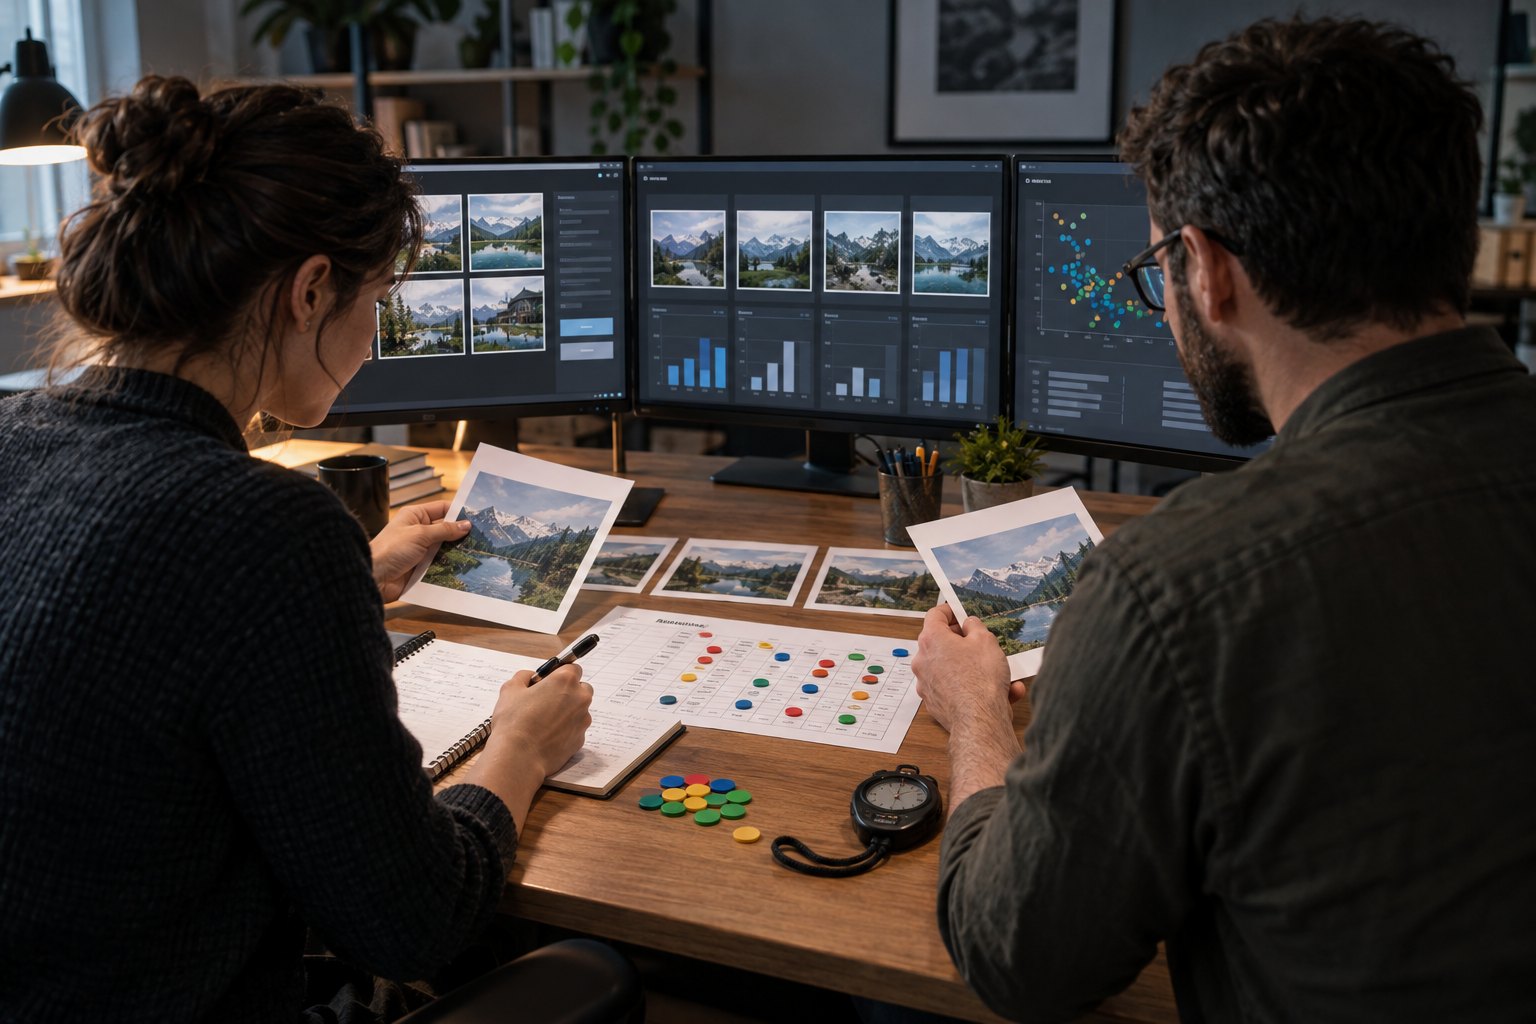
Choose three realistic but non-sensitive cases: a common one, a difficult one and one the tool should decline or flag. Use identical cases in two services.
Evidence to keep
Record expected outcomes, errors, human time, observed cost and reviewer disagreements.
Make the decision
Select the service that meets thresholds defined before testing; do not rewrite the rubric after seeing the results.
A balanced scorecard
Quality
Is the result accurate, complete and compliant with instructions?
Effort
How much human preparation, review and correction is required?
Cost
What is the total cost per validated result, not per generation?
Control
Can administrators audit, export, delete and leave the service?
General and professional tools to put through the test
Use this selection to build a shortlist. Verify the exact plans, regions, limits and account conditions on official sources.
ChatGPT
general assistant
OpenAI · US
Visit official site
NVIDIA NIM
model hosting
NVIDIA · US
Visit official site
Microsoft 365 Copilot
office assistance
Microsoft · US
Visit official site
Claude
long-document analysis
Anthropic · US
Visit official site
Microsoft Foundry
cloud AI platform
Microsoft · US
Visit official site
Gemini for Workspace
Google Workspace assistance
Google · US
Visit official siteHow is this selection produced?
Active services are distributed across guide-related categories, then ordered by editorial highlighting and internal score. This does not assess security, compliance or performance on your use case. Methodology.
Explore tools for this task
- Duck.ai — Explore ideas, rephrase non-sensitive text or compare answers without installing a model. For documentary research, require accessible references instead of treating fluent answers as evidence.
- Gemini Notebook — Explore a set of reports, prepare a synthesis or find useful passages in a defined corpus. Select relevant documents and remove obsolete versions first.
- AWS Bedrock — Evaluate models inside an AWS application, connect a corpus or organize calls with access controls. Define region, latency, budget and supervision requirements first.
- ChatGPT — Prepare a note from two public reports or explore a table with known totals. Specify columns, units, dates and passages to preserve. Writing tasks and calculation tasks require different checks.
- Claude — Prepare texts following one style guide or analyze a reference dossier. Separate background documents, style rules and task-specific instructions so you can understand what influences the output.
- Gemini — Read a report or query a limited set of authorized files. Define whether the answer must cover prose, numerical data or comparisons. Do not confuse file contents with a web search.
Related tool families
Frequently asked questions
How many cases should be tested?
Five to ten cases covering normal work and major risks provide an initial signal. A material decision then needs a larger sample monitored over time.
Can scoring be automated?
Yes for objective format or calculation checks. Relevance, nuance and risk often require human assessment, ideally with tool names hidden.
When should the benchmark be repeated?
Repeat it after a model, price, data-policy or internal-process change, or when observed quality drifts. Also schedule a periodic review.
The references below expand on the concepts and checks discussed. Scenarios and trial frameworks remain editorial proposals; provider documentation describes its own product rather than an independent benchmark.